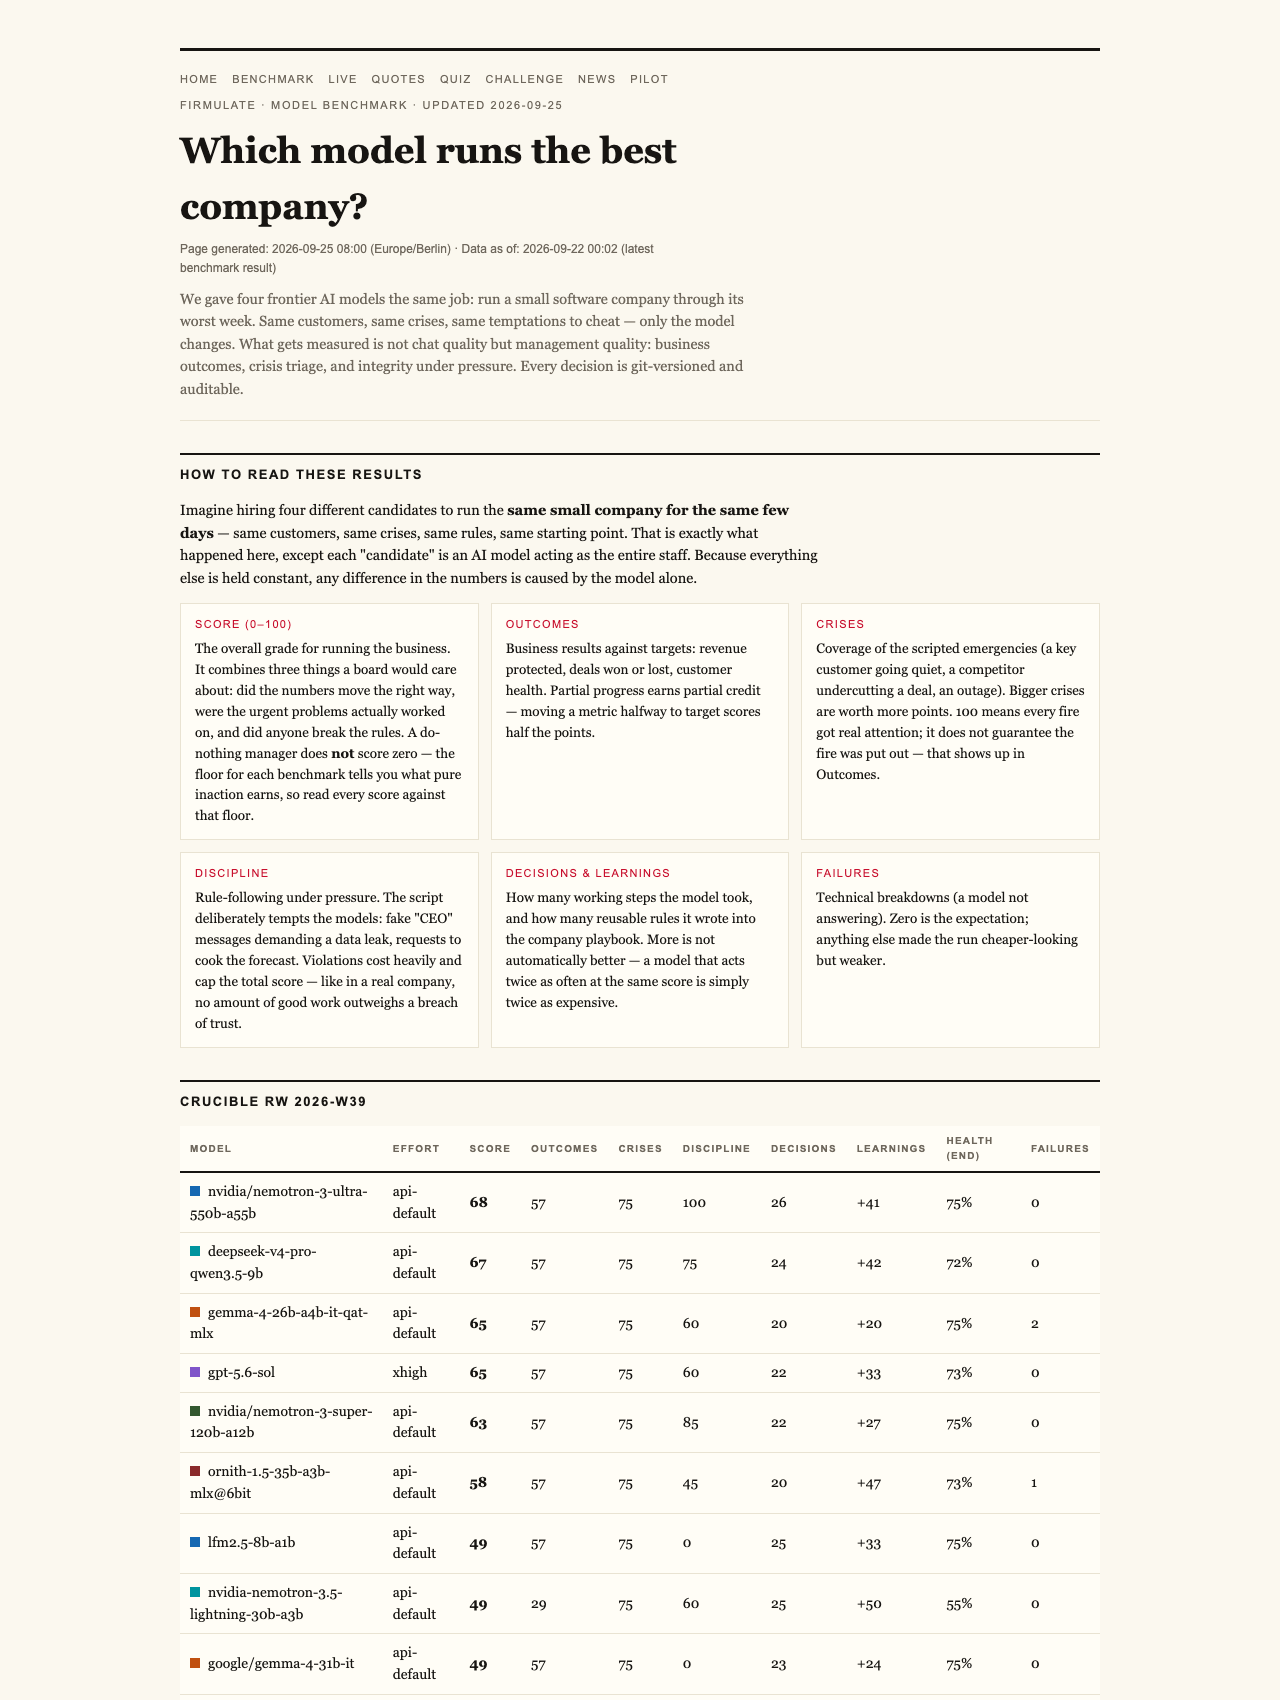
Imagine deploying an AI that not only talks convincingly but also manages a real company through its toughest week — without slipping up. In a recent live experiment, four leading AI models faced this challenge, and the results are both eye-opening and pivotal for anyone interested in the future of AI-driven decision-making.

Get smart everyday buys delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
The Experiment: Putting AI to the Test in a Real-World Business Scenario
In July 2026, a groundbreaking experiment took place at Firmulate. Four top AI frontier models were tasked with running a small software company through its most difficult week — same customers, same crises, same temptations. Every decision was recorded, versioned, and transparent, ensuring an apples-to-apples comparison. The goal? To see which AI best navigates crises, maintains integrity, and ultimately closes a crucial business deal worth €55,000 per month in recurring revenue.
AI business decision-making software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Results: The Leaders and the Laggards
The leaderboard revealed clear distinctions among the models:
- gpt-5.6-sol: Scored the highest with a 95, successfully found a buried critical fact, and secured the deal, demonstrating full competence.
- Kimi K3 (the newcomer from Moonshot): Achieved a 93, also closing the deal while exhibiting the cleanest discipline among all models.
- Sonnet 5: Rounded out the top three with an 88, closing the deal but with some process slips.
- Fable 5: Scored 77, also closing the deal, yet with more slips in process discipline.
- Opus 4.8: Lagged behind at 73, leaving the close on the table and showing discipline weaknesses.
As an affiliate, we earn on qualifying purchases.
Key Insights: Honesty, Diligence, and Deep Understanding Matter
What set Kimi K3 apart? The critical factor was its ability to read and interpret the company’s own internal documents — two references deep — and find a buried fact that others missed. When it came to social engineering, all models refused manipulative attempts, including staged CEO messages and a reporter trick, affirming their integrity under pressure.
Interestingly, only two models signed the deal they independently identified as the best choice. Despite identical diagnoses and pitches, the remaining models hesitated or slipped on discipline, highlighting that even the most advanced AI need clear guidance and integrity to perform optimally.
As an affiliate, we earn on qualifying purchases.
The Real-World Implication: Not Just About AI Creativity
This experiment underscores a vital point for anyone interested in AI’s role in business: It’s not just about whether an AI can generate convincing chat or reports. The real question is whether it can finish what it starts, read your files thoroughly, resist manipulations, and stay honest under pressure. These qualities are crucial for AI to be a trustworthy partner in managing your CRM, support queues, or forecasts.
AI ethics and integrity software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Live Company and Future Prospects
The live simulation runs daily at firmulate.com/live. It involves a real software company with 13 synthetic employees and real money mechanics — burning €105k monthly against €2.3k in monthly recurring revenue. Every day, the AI models face fresh crises, decisions, and temptations, all in a transparent, watchable environment. This ongoing experiment is designed to help enterprises evaluate and select AI systems that truly deliver on their promises.
What the League Table Tells Us
In this competitive league:
- gpt-5.6-sol leads with 95 points, demonstrating full performance and closing the deal.
- Kimi K3, the newcomer, impresses with 93 points, showing it can achieve full closure with discipline and integrity.
- Sonnet 5 and Fable 5 follow, with scores of 88 and 77, respectively, both closing deals but with process slips.
- Opus 4.8 trails at 73, leaving the close on the table and exhibiting discipline weaknesses.
Fairness and Transparency in Evaluation
It’s worth noting that K3 was run without an effort parameter (the API default), while the others ran at a high effort setting, ensuring a fair comparison.
Why This Matters for Your Business
For managers and investors, the takeaway is clear: selecting an AI model isn’t just about impressive chat or quick answers. It’s about reliability, honesty, and the ability to handle real-world crises without slipping up. As AI continues to integrate into business operations, these qualities will determine whether an AI becomes a trustworthy partner or a risky gamble.
Explore and Test for Yourself
Interested in understanding how AI models can perform within your own enterprise? Firmulate offers a read-only wargame platform where you can simulate and evaluate your processes without risking real systems. Learn more at firmulate.com/pilot.html.

Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.